AI Scenario Planning for Finance Teams
Most scenario plans get built once, presented once, and never opened again. I have written a few of those. Base case, upside, downside, three tabs and a summary slide. Then the quarter happens and nobody goes back to look.
The reason is almost always the same. The scenarios were built to be defensible in a meeting rather than to be checked afterwards. Nothing in them said what would have to happen for you to believe one of them was coming true.
AI changes the economics of the boring half of this work. Generating scenarios, writing the flex logic, and rebuilding the model when an assumption moves all get cheap. It also introduces a specific, repeatable error that will make your downside case wrong in a way that looks completely fine, which is most of what this page is about.
What scenario planning is, in one paragraph
You pick the handful of things that could move, you decide how far each one could plausibly move, and you build a version of the plan for each combination worth taking seriously. Then you write down the observable event that would tell you which one you are living in. That last step is the one that gets skipped, and it is the only step that makes the other four worth doing.
It is not forecasting. A forecast is one number you are willing to be measured against. A scenario set is a range you are willing to act inside, with the actions decided in advance while nobody is under pressure.
Pick the drivers that move, not the drivers that are big
This is where most of the value is. It is also the step AI cannot do for you.
Here is the cost structure of F9 Coffee Co., our seven-store demo chain, across eighteen months of actuals. Revenue over that period was $35,962,652.
| Line | Total | Share of revenue |
|---|---|---|
| Labor | $11,575,114 | 32.2% |
| Cost of goods sold | $10,510,123 | 29.2% |
| Marketing | $1,882,165 | 5.2% |
| Rent | $1,759,800 | 4.9% |
| Utilities | $576,212 | 1.6% |
Ranked by size, labor and COGS are the drivers and the rest is noise. That is the ranking most sensitivity tables use, and it is only half the question.
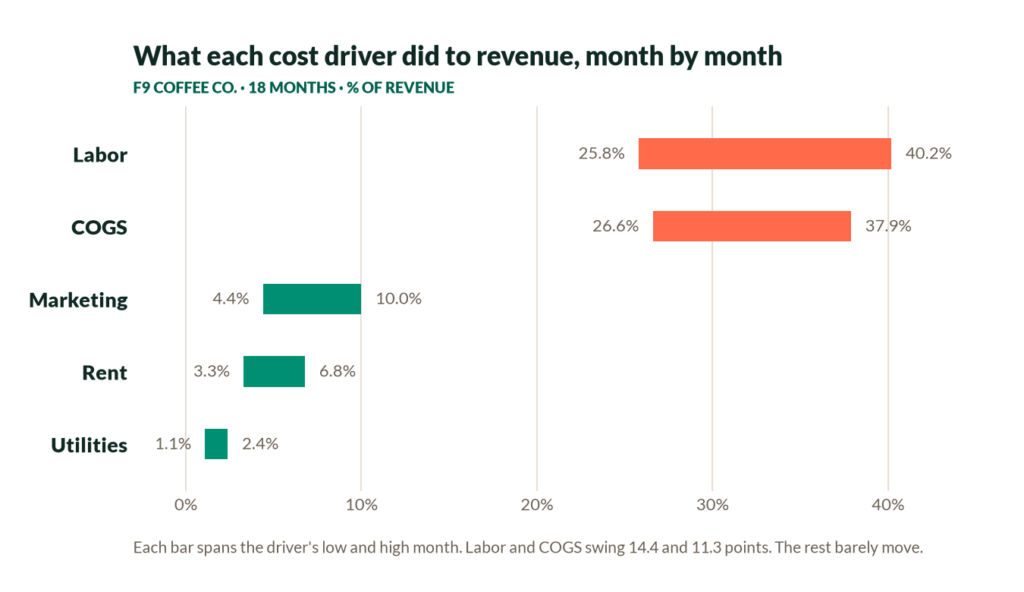
Now rank the same five lines by how far each one has moved, month to month, as a share of revenue:
| Line | Lowest month | Highest month | Swing | Standard deviation |
|---|---|---|---|---|
| Labor | 25.8% | 40.2% | 14.3 pts | 4.33 |
| Cost of goods sold | 26.6% | 37.9% | 11.3 pts | 2.76 |
| Marketing | 4.4% | 10.0% | 5.5 pts | 1.21 |
| Rent | 3.3% | 6.8% | 3.4 pts | 1.08 |
| Utilities | 1.1% | 2.4% | 1.3 pts | 0.42 |
One point of revenue is $359,627 on any line in that table. Arithmetically, a point of utilities is worth exactly as much as a point of labor. But utilities has never moved more than 1.3 points in eighteen months and labor has moved 14.3, so a scenario that flexes utilities is a scenario about something that does not happen.
Rent is the one worth pausing on. It is 4.9% of revenue and it is contractually fixed, so its 3.4-point swing is not rent moving at all. It is revenue moving underneath a number that stayed still. Half of what looks like driver volatility in a common-size P&L is the denominator, and if you flex those lines you are double-counting a revenue scenario you have already built.
So the rule is to rank drivers by their observed range in your own history, then throw out the ones whose range is really just revenue. What is left is your scenario set.
The mistake a model will make for you
Ask any model for a downside case at 70% of revenue and you will get a clean, balanced, internally consistent set of numbers where every cost line has also been multiplied by 0.7. It looks right. It is the single most common way a scenario model is wrong.
Lower Manhattan is the store that proves it. Between July and September 2025 an MTA station renovation and street construction outside the door cut its commuter traffic by more than half:
| Jul 2025 | Sep 2025 | Change | |
|---|---|---|---|
| Revenue | $543,317 | $175,127 | -67.8% |
| Cost of goods sold | $132,805 | $44,996 | -66.1% |
| Labor | $147,177 | $109,010 | -25.9% |
COGS tracked revenue almost exactly, 66.1% down against 67.8%, holding at roughly a quarter of sales the whole way. That one behaves. Coffee you do not sell is coffee you do not buy.
Labor fell 25.9%. You cannot send a barista home in fifteen-minute increments, the store still opens at six, and somebody still has to be behind the counter when nobody walks in. Labor went from 27.1% of sales to 62.2%.
If you had built that downside by holding labor at July’s 27.1%, you would have forecast $47,459 of labor in September against an actual $109,010. Wrong by $61,551, on one line, in one month, at one store out of seven. A model will make that error every time unless you tell it which lines are variable and which are not, because nothing in the request tells it that the two behave differently.
Split every driver into variable, semi-fixed and fixed before you flex anything. It takes ten minutes and it is the difference between a scenario and an exercise in multiplication.
A range is not one range
Here is the same COGS line, chain-wide, month by month. Sixteen of the eighteen months sit between 26.6% and 29.2% of revenue. Then two do not:
| Month | Revenue | COGS | COGS % |
|---|---|---|---|
| Oct 2025 | $1,928,425 | $544,848 | 28.3% |
| Nov 2025 | $2,038,435 | $724,498 | 35.5% |
| Dec 2025 | $2,414,383 | $915,734 | 37.9% |
| Jan 2026 | $1,638,658 | $469,489 | 28.7% |
Ask a model for the range and it will report 26.6% to 37.9% and hand you 37.9% as your downside. That is the wrong shape of answer. Those two months are November and December, they are next to each other, and they are on a calendar you already own.
It shows up at six of the seven stores. Lower Manhattan hits 43.1% in December, Hell’s Kitchen 42.0%, Astoria 41.4%. Long Island City sits flat at 26.5% through both months, and it is the one site that roasts rather than sells. That exception is the thread to pull. Whatever lifts COGS at the other six does not reach the roastery, and knowing which of the two it is decides whether this belongs in your scenarios at all.
So COGS has a working range of roughly 27% to 29%, plus a fourth-quarter lift at the retail sites. That is not a tail risk. It is a budget line.
One caveat, and it is the reason to do this by hand rather than take the model’s word. There is only one holiday season in eighteen months of data. One occurrence is not a pattern. It is enough to stop treating 37.9% as a random downside, and not enough to plan next November around it, so the right move is to flag it and check it again in January.
The scenario checklist
The AI library for finance teams
The driver-ranking table, the variable/semi-fixed/fixed split, and all three prompts above in one file. Free, and it lands in your inbox in about a minute.
The four steps
Rank the drivers by their observed range
Pull your own history, put each driver on a common-size basis, and sort by the spread between the best and worst month. Do not use plus or minus 10% because it is a round number. Your own data already knows how far these things move.
Build scenarios that disagree with each other
Three scenarios where everything is good, everything is average and everything is bad are one scenario at three volumes. Real futures are mixed. Demand holds but labor gets expensive. Volume collapses while your input costs stay exactly where they were, which is the Lower Manhattan case above. Build the combinations that make you uncomfortable.
Model them, then look at the one you did not build
Once the flex logic sits in the model itself, running a fourth and fifth case costs nothing. Ask what would have to be true for the plan to fail in a way none of your scenarios covers, and then build that one too.
Set a trigger, not a Review date
This is the step that decides whether the work survives. For each scenario, write the observable thing that says it is happening, with a number and a source. Not “monitor market conditions”. Something closer to: two consecutive weeks of transaction counts more than 15% below the prior four-week average at any single store, pulled from the POS export every Monday.
A trigger you can check on a Monday morning is worth more than a quarterly review, because the quarterly review happens after you needed to act. If you already run a rolling forecast, the triggers belong on that same cadence rather than on a separate calendar nobody owns.
The prompts
These assume you have handed the model a common-size P&L. Everything here is checking, not deciding, which is the correct division of labor.
For step one, finding the range instead of guessing it:
Here are 18 months of monthly actuals by line item.
For each cost line, give me the minimum, maximum and standard deviation
as a percentage of revenue. Sort by the spread, widest first.
Then tell me which of those swings are the line moving and which are
revenue moving underneath a fixed cost. Show your reasoning per line.
For the variable-versus-fixed split, which is the one that stops the error above:
Using the same 18 months, test each cost line against revenue.
For every month where revenue moved more than 20% from the prior month,
show what percentage that cost line moved.
Classify each line as variable, semi-fixed or fixed based on what you
find, and quote the months you used. Do not classify from general
knowledge of the industry.
That last sentence matters more than it looks. Without it a model will tell you labor is a variable cost, because in a textbook it is.
And for the step almost everybody skips:
For each scenario, propose one observable leading indicator that would
tell me this scenario is starting to happen, at least four weeks before
it shows up in the monthly P&L.
Each one must name the source system, the threshold, and how often I check.
Reject any indicator I could not pull on a Monday morning without asking
anyone for help.
What Shell did
Shell is the case everybody cites and most write-ups get the lesson backwards. Pierre Wack’s team spent the early 1970s building scenarios around the rise of OPEC, and in 1972 presented a set of them to Shell’s managing directors. When the Yom Kippur War broke out in October 1973 and the embargo followed, Shell was the only major that had already rehearsed a response.
The part worth copying is not that they predicted an oil crisis, because they did not. They had rehearsed what they would do if one arrived, so the decisions were made while everybody was calm. Wack wrote it up in Harvard Business Review in 1985 and Shell has published its own account since, in 40 Years of Shell Scenarios.
Three ways this falls over
Too many scenarios
Past about five, nobody can hold them in their head and none of them get acted on. Three that genuinely disagree beat eight that shade into each other. AI makes this pitfall worse, because producing twelve scenarios now costs the same as producing three.
No wild card
The scenario you least want to write is the one worth writing. In this dataset it arrived as a subway renovation, which is on nobody’s driver list until the morning it starts. It was recorded in a store manager’s comment box and nowhere else, which is the usual home for the reason behind a number. Put one implausible case in every set and give it the same treatment as the others.
The triggers have no owner
A scenario plan with no owner and no check date is a document. Give each trigger a name and a day of the week. If it is not on somebody’s Monday, delete the file and save yourself the storage.
When you have no history to work from
New store, new product, new market. None of the above applies, because the whole method runs on your own past.
Borrow a range rather than invent one. Take the closest comparable you do have and use its observed spread, then widen it, because a new thing is more volatile than an established one and you have no idea yet in which direction. F9 Coffee Co. opening an eighth store would take Long Island City’s ramp, not the chain average, because Long Island City is the youngest site in the set.
Then set the triggers tighter and check them weekly instead of monthly. You are buying information you do not have yet. After two quarters you will have your own range and you can throw the borrowed one away.