How To Build A Fabric Data Agent On Your Power BI Model
Your Power BI dashboard answers the questions you thought of when you built it. Everything else lands on you.
Somebody wants January cash. Somebody wants to know which locations missed budget and by how much. The report doesn’t have that view, so you open the model, write the filter, read the number, and send it back. Ten minutes, five times a week, forever.
A Fabric data agent puts a chat window on top of the semantic model behind that dashboard. Your team asks in plain English, and the answer comes back with the query that produced it attached. I built one end to end on a model I already had published, and the first working version took under ten minutes.
Here’s all of it, including the setup nobody writes down, the two places you teach it your business rules, and the error that stopped me cold the first time. If you’d rather watch me build it, the full walkthrough is here.
What a Fabric data agent is
A chat interface sitting on data you already keep inside Microsoft Fabric. It’s read only, it can’t change anything, and every answer arrives with the query it wrote to get there. That last part is the reason it belongs in a finance workflow rather than a demo.
You can point one at a lakehouse, a warehouse, a KQL database, a mirrored database, an ontology, or a Power BI semantic model. A single agent holds up to five sources in any mix. If most of those words mean nothing to you, that’s fine, and it’s not a gap you need to go and close. Most finance teams have exactly one of them, and for a lot of us it’s the last one on the list. The rest of the AI in Power BI stack sits on the same foundation.
Mirroring is worth knowing about even if you skip everything else here. If your company’s data lives in Snowflake, or on AWS, or in a warehouse somebody else owns, Fabric can mirror it in rather than making you move it. That’s how a finance team gets to any of this without a migration project attached.
Why the semantic model beats the other sources
A semantic model is the thing sitting behind your Power BI report. If you have a published dashboard, you already have one, whether or not you’ve ever called it that.
It wins for finance work because the thinking is already done inside it. The data is clean. The relationships are set. The measures are written, which means somebody already decided what revenue means, what counts as a store, and which version is actuals.
An agent pointed at raw tables has to work all of that out on the fly, and it will guess. There’s hard evidence on how that goes. On Spider 2.0, a benchmark built out of real enterprise data warehouses, the strongest setup the researchers tested solved 21.3% of the tasks. That same setup scored 91.2% on the older academic benchmark with its tidy little schemas. Real corporate data is where plain-English-to-query falls apart, and a well-built semantic model is the layer where somebody already cleaned that up for you.
If you’ve ever watched two people pull two different revenue numbers out of the same system, you know why this matters. The model is where you settled that argument. The agent inherits the settlement.
What you need before you start
Four things. One of them costs money.
Start with a Power BI semantic model published to a workspace. If your reports live at app.powerbi.com, they’re already in Fabric, whether or not anyone at your company uses that word. Nothing to move.
Then a paid Fabric capacity, and this is the one that catches people. Microsoft’s prerequisite reads “a paid F2 or higher Fabric capacity,” and the word doing the work in that sentence is paid. Trial capacity won’t run a data agent. A Microsoft 365 Copilot license doesn’t cover it either. F2 is the smallest paid SKU, and you create it in the Azure portal, which is Microsoft’s cloud infrastructure layer, the same tier of the stack as AWS or Google Cloud. Costs are further down.
The AI tenant settings have to be switched on. They’re off by default because they consume capacity, so Microsoft makes you opt in deliberately rather than by accident.
And Read permission on the model. Not Build, not workspace membership. Read. Microsoft’s setup documentation is unusually blunt about it: “Build permission isn’t required, and users don’t need access to the workspace where the semantic model resides when using it via a data agent.” So if your BI team owns the model and you can’t write to a single thing in that workspace, you can still do this. Worth knowing before you go and ask for access you don’t need.
Turning on the tenant settings
From the Fabric portal, click the settings wheel, then Admin portal. Filter by keyword and search “agent”. Everything you need lands on one screen.
- Under Copilot and AI, confirm users can use Copilot is enabled for the entire organization.
- In the same block, allow Azure OpenAI processing outside your capacity’s geographic region. The AI has to run where the capacity exists. If you’re in the EU, this is the setting to read slowly with whoever owns data residency at your company.
- Allow Microsoft sub-processors to process the data as well.
- Under Microsoft Fabric, switch on everything matching “agent”.
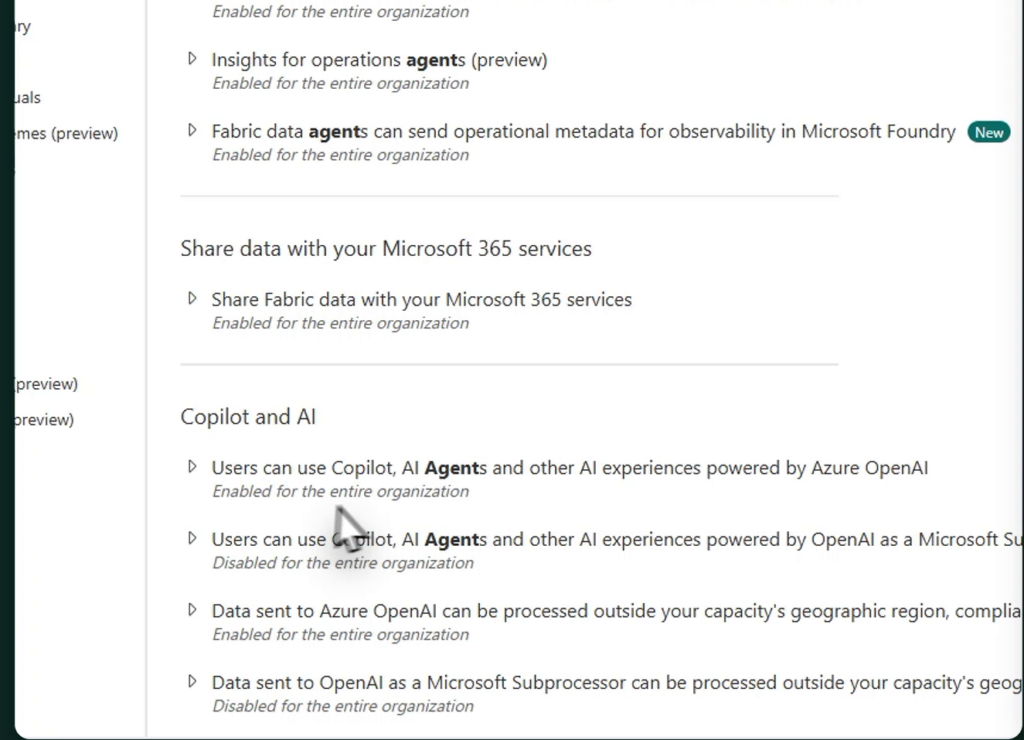
That’s the setup. Once those are on, your capacity is ready and you never touch this screen again.
Building the agent
Work in the workspace where your data already lives. It saves a lot of friction later.
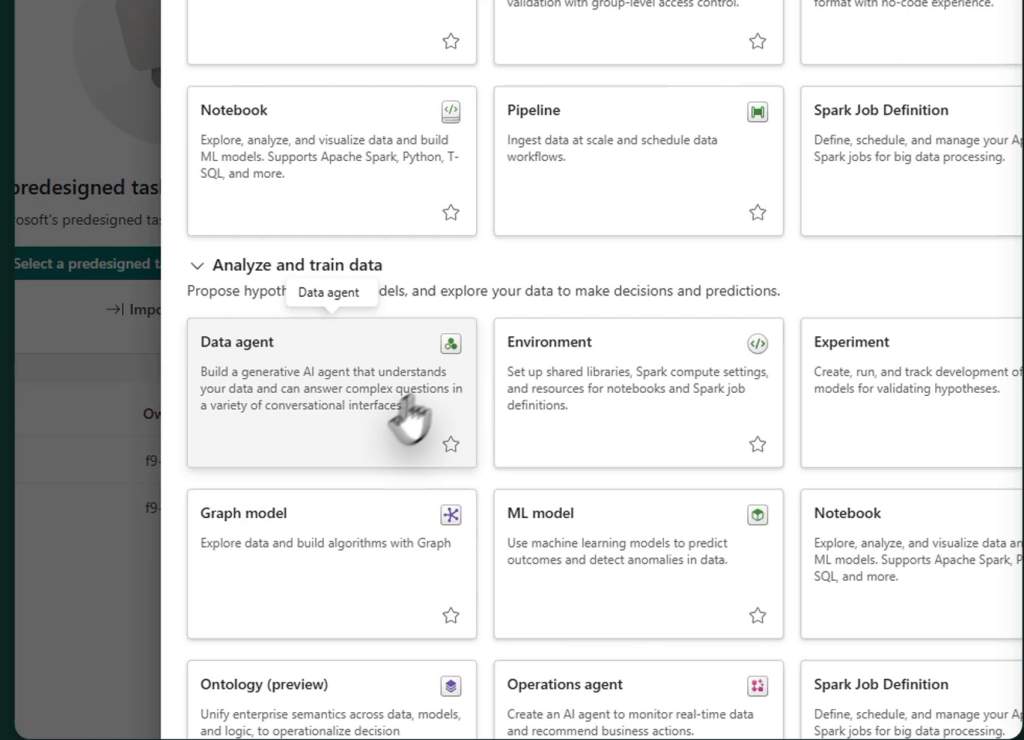
- Click New item in the workspace ribbon. The list is long and most of it will never matter to you. It’s grouped by job, so scroll to Analyze and train data.
- Choose Data agent. The tile reads “build a generative AI agent that understands your data and can answer complex questions.”
- Name it and create. I called mine F9 Finance Analyst.
- Skip the tour when it offers one.
The interface is simpler than it looks. Explorer on the left is where your data goes. The middle is the chat, plus the controls for what the agent can do. Along the top sit a few tools: adding capabilities like the code interpreter, building the agent with AI, and testing it.
Connecting the model and picking tables
Click Data source and pick your semantic model. Anything sitting in your Fabric capacity shows up here, whichever source type it is.
Once it’s added, the middle of the screen turns into a chat window that looks like every other AI tool you’ve used, with your data listed down the side. Now choose which tables the agent is allowed to see. I gave mine six: financials, bank balances, a date table, location, GL entries, and travel and expense.
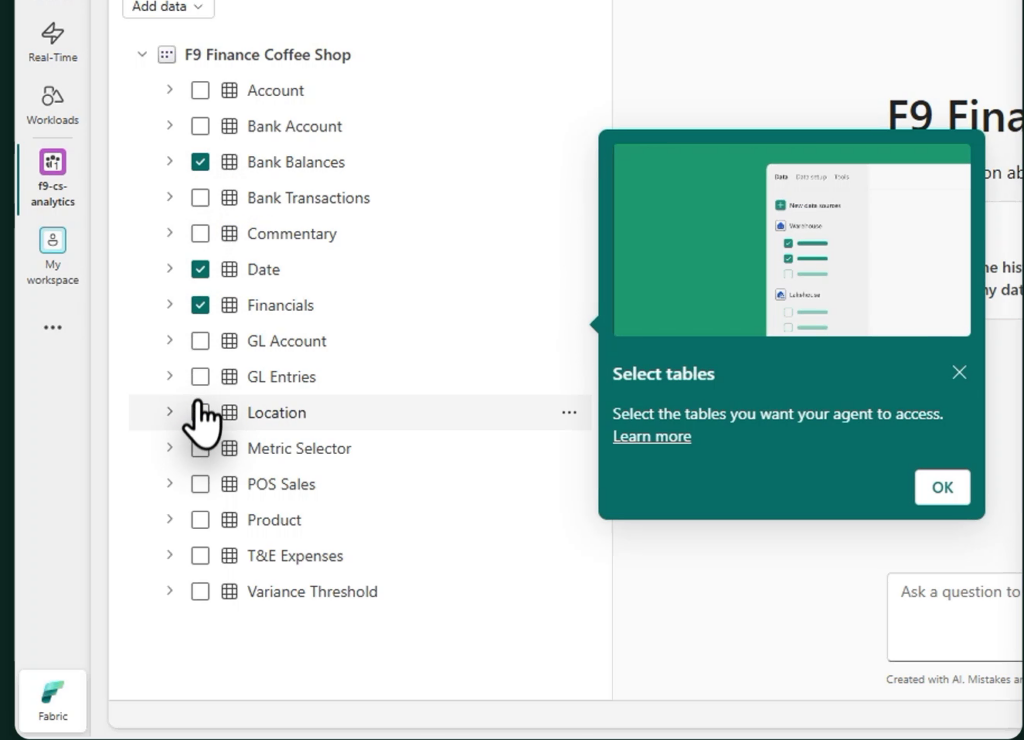
Be stingy here. Every table you check is one more thing the agent has to reason about before it answers, so a narrower selection produces better answers. That runs against instinct and it holds up, in my testing and in Microsoft’s own best-practice guidance. Start with what your questions will need and add more later.
That’s the build finished. Empty workspace to working agent, and that’s the whole of it.
Asking it a real question
Everything from here runs on F9 Coffee Co., a demo dataset I built for teaching. The numbers are invented. The behavior is not.
My first question was one nobody had built a report page for: which locations came in under their operating budget in the first half of the year, and by how much. It came back in about 25 seconds with the locations, the amounts, and a written description of how it got there.
Reading the DAX it wrote
Expand the step underneath the answer and the query is sitting right there. Measures show up in square brackets, which tells you it used the definitions already in your model instead of inventing its own arithmetic. Operating income, budget, variance, all pulled from DAX somebody already validated.
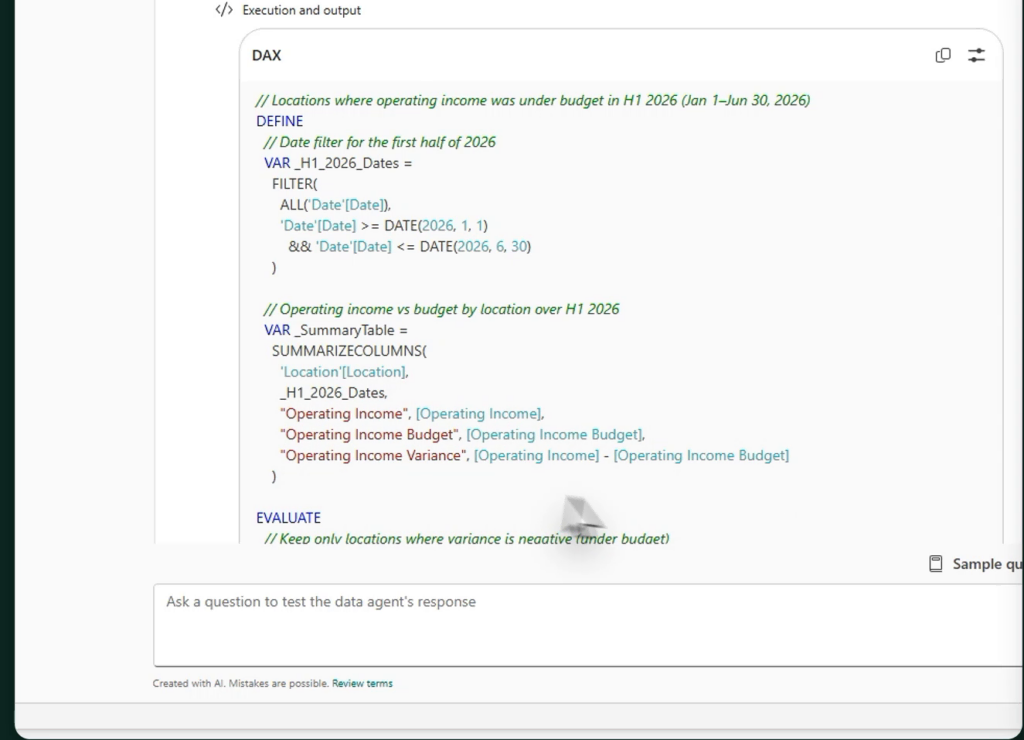
For anyone who has to stand behind a number, that expandable step is the part that counts. The FRC’s guidance on AI in audit lands in the same place: how much explainability you need depends on what the output is being used for, and for a number going into a board pack the bar is high. Here you get the number and the query that produced it, side by side, before anyone asks.
Where it gets things wrong
My second question was simpler. Total revenue for a single month. It answered correctly against the raw data, and the answer still wasn’t the number I’d hand a CFO.
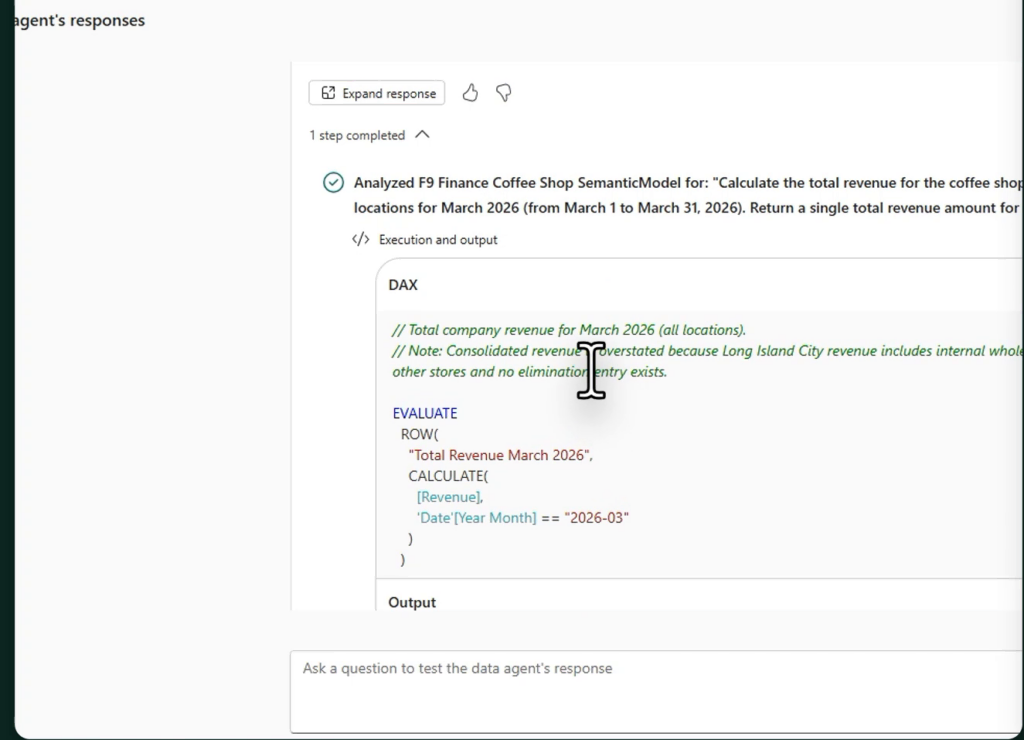
It surfaced a note I’d left inside the semantic model flagging that consolidated revenue is overstated, because it doesn’t exclude internal wholesale sales between locations. So it read the flag and repeated it, which is good behavior. It didn’t adjust for it, because nothing had told it to.
That’s an untuned agent. Right about the data, incomplete about the business. Closing that gap is the rest of this article.
FREE AI LIBRARY
Want the instruction block I used?
Every prompt from this build, plus the prompts and templates from everything else I make, sit in the AI Library. It’s free, and it comes with Finance AI Insider, my weekly newsletter on FP&A automation.
Teaching it your business rules
Nobody takes AI off the shelf and runs it as shipped. You give it context. With a Fabric data agent there are two separate boxes for that, they behave differently, and the difference is the opposite of what the interface suggests.
Prep data for AI, on the model
This one lives on the semantic model rather than the agent. Open your report, switch from view mode to edit, and click Open semantic model. Two buttons appear: Copilot, and Prep data for AI.
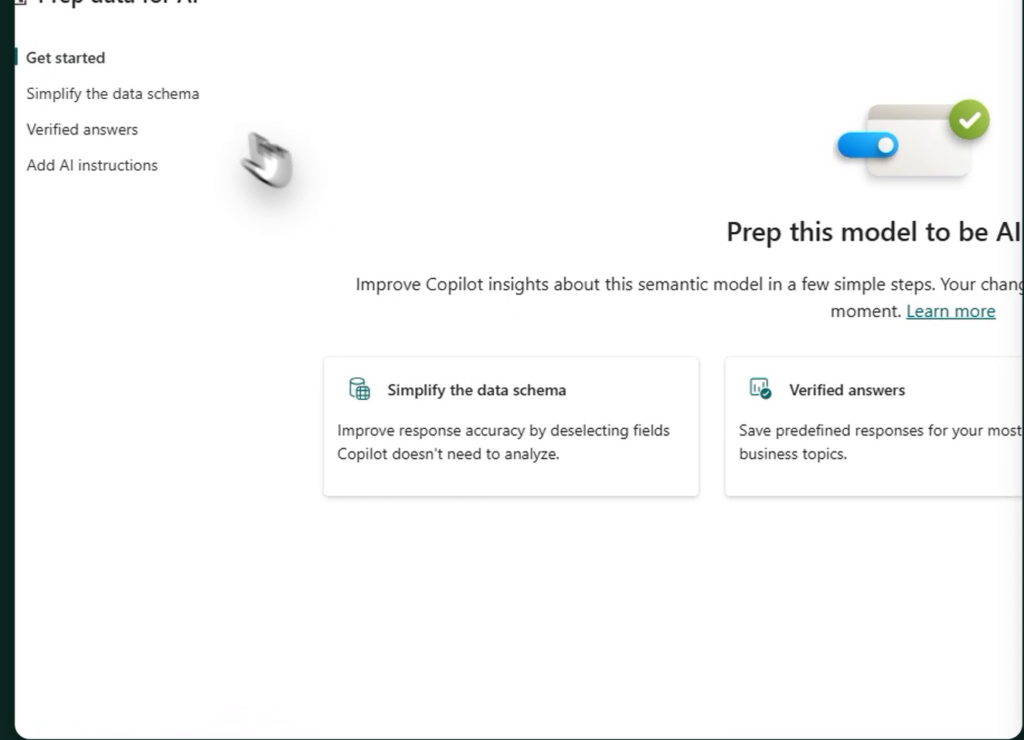
| Stage | What it changes |
|---|---|
| Simplify the data schema | Which tables, columns and measures the AI is allowed to consider |
| Verified answers | Locks a set of question phrasings to a visual you already trust |
| Add AI instructions | Business context and terminology written straight onto the model |
All three reach your data agent, not just Copilot inside Power BI. Microsoft’s semantic model guidance for data agents maps the query flow and lists AI instructions, verified answers and the AI data schema as direct inputs to DAX generation.
Verified answers are the one to reach for when a question has to come back the same way every time. You point a handful of phrasings at an existing visual, and the agent reads that visual’s columns, measures and filters and shapes its query around them. You get a DAX query built to a template you already approved, on the questions where improvising is a problem.
The same screen drives Copilot inside Power BI, so this work does double duty if you’ve already gone through how to set up Power BI Copilot.
Agent instructions, on the agent
In the agent, open Agent instructions. It’s a plain markdown box with 15,000 characters to play with, and it works the way a system prompt works in any other AI tool. Markdown, if you haven’t used it, is stripped-down text formatting that models read cleanly.
"Revenue" with no qualifier means the Revenue measure. Do not substitute
POS Revenue, Revenue ex Intercompany, or any year-to-date variant unless
the user names it.

Williamsburg has no activity before March 2025 and Long Island City has
none before September 2025. Those months are pre-opening, not zeros.
Exclude them from any average or comparison period.

Long Island City revenue includes internal wholesale sales to other
locations with no elimination posted. Say so whenever a question
compares locations on revenue.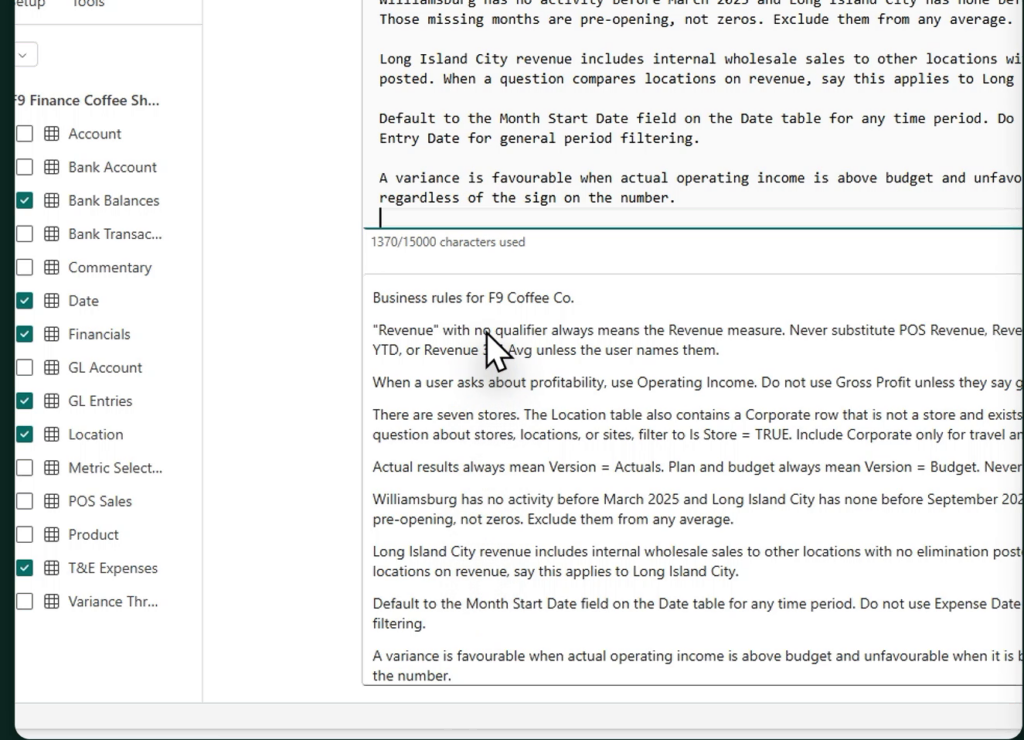
I tested it by asking for year-to-date performance at one location against the prior year. Two things happened. The analysis showed the agent had picked up the pre-opening rule and quoted it back before doing anything else. Then it declined to answer, because that location only began trading partway through the prior year, so there was nothing to compare against.
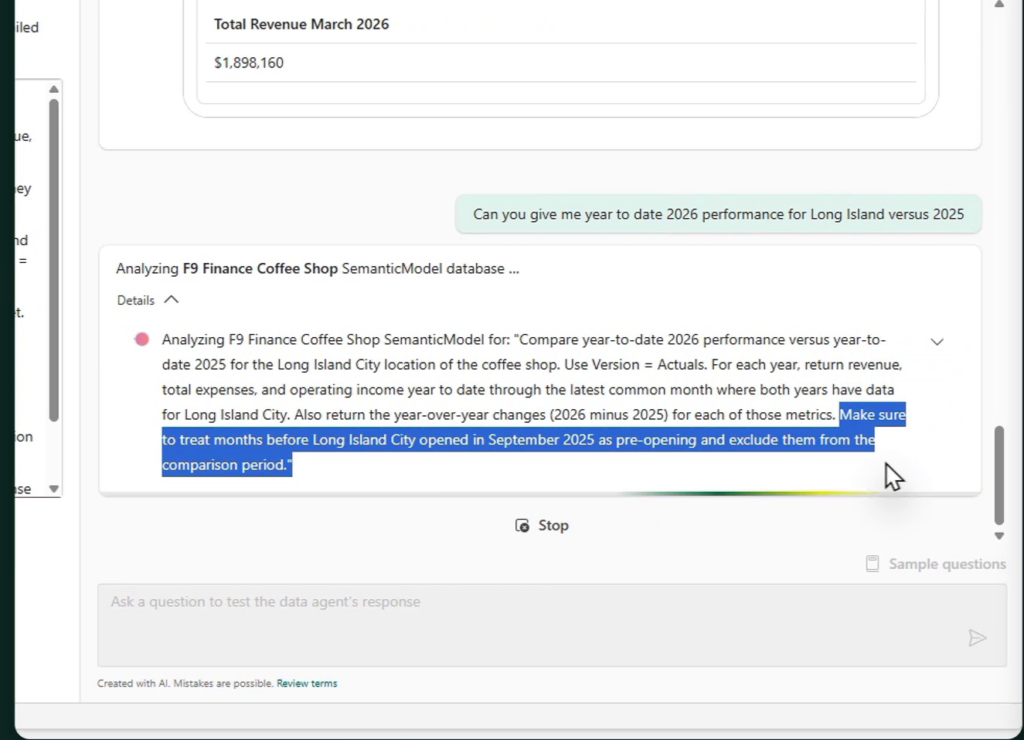
A declined answer with a reason attached beats a confident wrong one every time.
Which box gets which rule
Here’s where the documentation surprised me, and it changed how I’d set this up. Microsoft’s semantic model guidance says the DAX generation tool “relies solely on the semantic model’s metadata and Prep for AI configurations” and “ignores any instructions you add at the data agent level for DAX query generation.”
So anything that should change how a query gets written against your model belongs in Prep data for AI. Metric definitions. Which date field to default to. Pre-opening months to exclude. Sign conventions on variance. All of it goes on the model, and Microsoft says so directly: “don’t add semantic model specific instructions at the data agent level.”
Agent instructions are for the layer above the query. Which source to route a question to when you have several, formatting preferences, common abbreviations, tone.
Which raises the obvious question about what you just saw on screen, where my agent-level rules clearly did something. Both things are true. The orchestrator reads agent instructions and uses them to decide how to respond, which is why mine declined that comparison. The DAX generator never sees them, so a query it writes will happily ignore the same rule. Put a business rule in the agent box and you get an agent that talks about it. Put it in Prep data for AI and you get a query that honors it.
If you only do one, do the model.
Multi-step DAX generation and the preview runtime
At the top of the agent there’s a runtime selector, and it defaults to standard. Standard is the generally available build: stable, predictable, updated infrequently. Preview is where new capability lands first, and where behavior can change between releases.
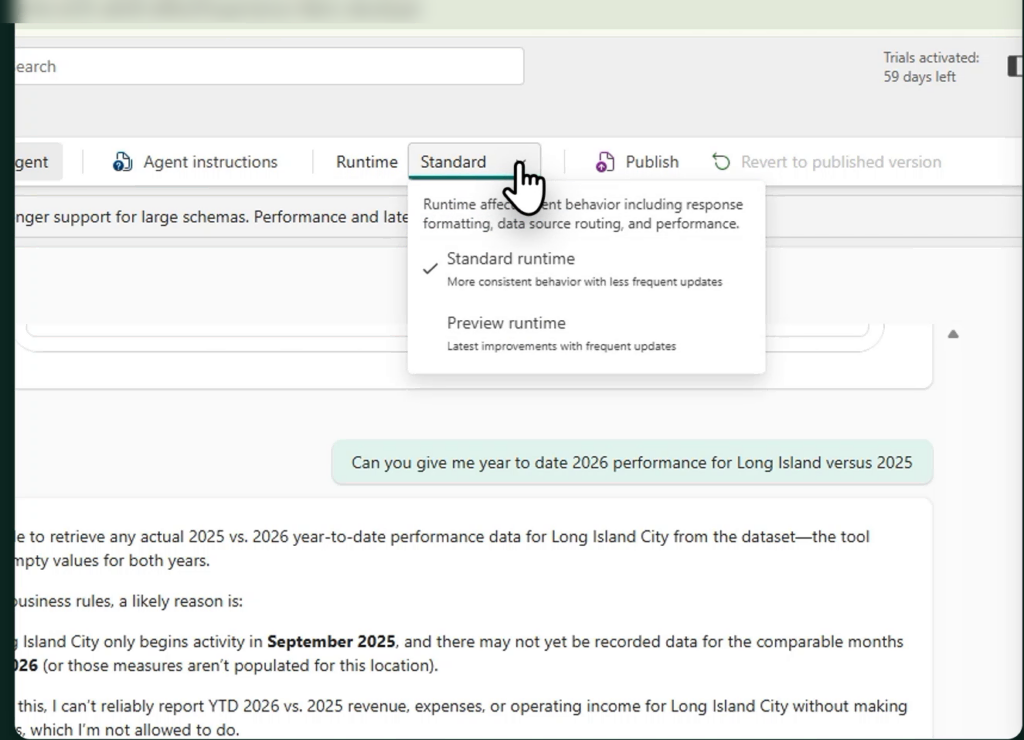
Switching to preview turns on advanced DAX generation. Standard writes one query and stops. Advanced runs a query, looks at what came back, resolves the ambiguity it found, and goes again across multiple reasoning steps. It also indexes the values inside your columns, so it picks real filter values rather than guessing at how your data spells things.
While you’re in there, go to Add tools and add the code interpreter. That’s a separate preview feature: a sandboxed Python environment the agent uses to analyze what it retrieved, run calculations the query language can’t do on its own, and draw charts. The two are built to work together.
Then give it something that needs more than one pass. I asked for two things in one prompt: evaluate location performance to find where costs are running inefficiently, then build a cost bridge for the worst performer showing what changed month over month.
You can watch it work. The first DAX pass goes in and comes back, and under standard generation that’s where your answer would stop. Instead it keeps going, runs the assessment, identifies the weakest location by operating margin, and then builds the expense bridge for that specific location off the back of its own first answer.
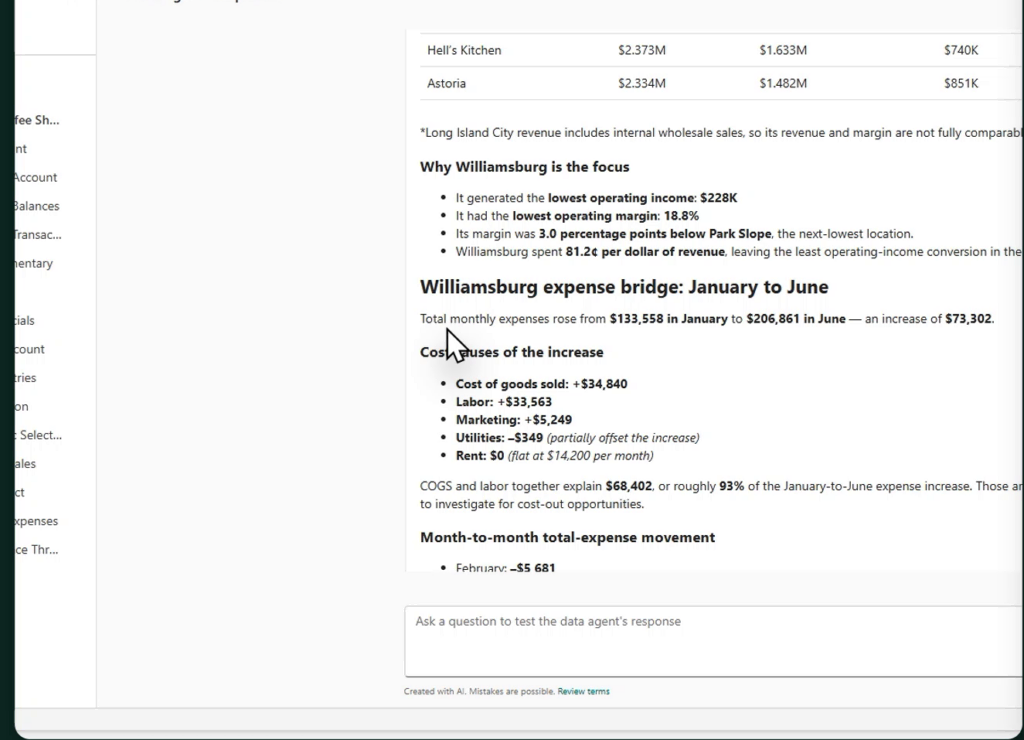
The read it produced was a real one. Labor and cost of sales climbing while marketing, utilities and rent held flat, with two months out of step with the revenue trend. That’s a cost-out starting point somebody can work from on Monday.
Nothing in that prompt could have been answered by a filter on an existing report page. That’s the line between a chat box and something worth building.
If you’d rather have the AI build the report than answer questions about it, building a Power BI report with AI is the other half of this.
What it does badly
Preview means preview. The code interpreter didn’t render my chart. Analysis there, numbers there, no visual.
It doesn’t explain causes, and Microsoft is refreshingly direct about that. “Why is our factory productivity lower in Q2” and “what is the root cause of our sales spike” are both on the out-of-scope list in the product documentation. A tool that answers those confidently is making something up.
Answers cap at 25 rows and 25 columns. Ask for everything and you’ll get a slice, and any follow-up question then reasons off that truncated slice rather than the full result. Start a new chat when that bites you.
The instructions are guidance rather than rules. Microsoft’s wording: AI instructions “are unstructured guidance that the LLM interprets, but there’s no guarantee it follows them exactly.” Short and specific beats long and thorough. It’s English only, too, and conversation history isn’t guaranteed to survive a service update.
And all of the tuning above only holds if the model underneath is sound. An agent sitting on a stale or badly built semantic model will produce confidently wrong answers faster than you could produce them by hand.
Common problems
“Capacity provided does not match capacity the AI Artifact is assigned to”
I hit this on the publish step and couldn’t find it documented anywhere. Fabric calls the data agent an AI artifact internally, and the item carries the capacity it was created under. If the workspace has moved to a different capacity since, the publish call arrives with one capacity while the item belongs to another.
The usual cause is the exact path a first-time user takes. Build the agent on one capacity, learn something about licensing, move the workspace, come back. Check the capacity under Workspace settings, License info. Sign out and back in, or use a private window, because a stale session holds the old capacity. Confirm the capacity is running and not paused. If the workspace genuinely moved, rebuild the agent where it now sits, which sounds heavy and is ten minutes. Your Prep data for AI work lives on the model, so none of that is lost.
Worth knowing that region matters too, and this one is documented. An agent can’t query a data source whose workspace capacity sits in a different region from the agent’s own capacity.
The data agent option is missing entirely
Almost always trial capacity. Data agents need a paid SKU, F2 or above.
Answers that are right about the data and wrong about the business
That’s the untuned state described above rather than a bug. It’s what Prep data for AI is for.
What it costs
Checked against Microsoft’s Azure pricing on 13 September 2026 for US West 2, Fabric capacity runs $0.18 per capacity unit hour on pay as you go. F2 is 2 capacity units, so roughly $0.36 an hour, or about $263 a month if you leave it running the whole time. A one-year reservation brings that down to around $156 a month. Prices vary by region, so check yours.
You can pause a pay-as-you-go capacity, and that’s the move while you’re learning. Turn it on for an afternoon, turn it off, pay for the afternoon.
Every question the agent answers consumes capacity units, so a full finance function running through an F2 will feel it. Scale the SKU to the usage.
There’s no data agent on trial capacity, and no route to one through a Microsoft 365 Copilot license, which is a separate bill covering separate things. If you’re not sure which of those you’re already paying for, Copilot for finance breaks down what each license includes.
Publishing it
One button. Publish makes the agent available to anyone with access to the workspace, or to anyone you share it with directly. You end up with two versions, a draft you keep refining and a published one your colleagues use.
One detail to catch before you click it: whichever runtime the agent is set to at publish time is the runtime the published version keeps using, until you republish with a different one. Publish on preview and your colleagues are on preview.
The thing to sit with is that publishing changes who the tool is for. Up to that point you’re the only person asking, and you know which questions are fair. After it, someone who has never seen the model is typing questions into it and forwarding the answers to their boss. That’s the argument for doing the instruction work first rather than treating it as polish.
If you have a published Power BI dashboard and a paid capacity, the build itself is an afternoon at most. The hour that earns its keep is the one you spend writing your business rules into Prep data for AI, because that’s the difference between an agent that answers and an agent you’d let a colleague quote in a meeting.
Pick one question your team asks every month that no report page covers, and build for that. Then go look at the wider set of AI tools for finance and see what else you can stop doing by hand.